Timeline
Every post and feed across this instance
-
Can I find RSS feed for a specific section in phpbb forum?
-
Fluent Reader on Linux/Wayland: working per-app UI scaling workaround (tested on KDE Plasma)
following solution was suggested by ChatGPT (OpenAI), tested and confirmed by myself. I am a Fluent Reader user on KDE Plasma/Wayland.
Feel free to give ChatGPT this Reddit thread as context and ask it to help turn the workaround into a proper Fluent Reader implementation.-------------------------------------
I wanted to increase the UI size of Fluent Reader without changing the scaling of my entire KDE Plasma desktop.
Tested setup:
- Fluent Reader 1.1.4
- Flatpak:
me.hyliu.fluentreader - KDE Plasma / Wayland
- 1920×1200 display
- KDE display scaling: 100%
- GPU acceleration / DRI enabled
The problem
Fluent Reader's UI is rather small at 100% desktop scaling.
Changing KDE's display scaling to 125% works perfectly, including Fluent Reader, but of course this scales the entire desktop.
I tried several common Electron/Linux approaches:
GDK_SCALEGDK_DPI_SCALEELECTRON_FORCE_DEVICE_SCALE_FACTORCtrl++--force-device-scale-factor=1.25--high-dpi-support=1 --force-device-scale-factor=1.25
The environment variables had no useful effect in my setup.
--force-device-scale-factorwas worse: under Wayland, Fluent Reader opened as a very small undecorated window.Effective workaround: scaling per CSS
During troubleshooting, ChatGPT (OpenAI) suggested a different approach: don't scale the Electron/Wayland window at all — scale Fluent Reader's web UI itself using CSS.
I tested this and can confirm that it works on my system.
Fluent Reader contains:
resources/app.asarAfter unpacking it, the UI styles can be found under:
dist/styles/Adding this to the end of
dist/styles/global.css:/* Custom Fluent Reader UI scaling */ body { zoom: 1.25; }and repacking
app.asargives me approximately 125% Fluent Reader UI scaling while KDE remains at 100%.The window remains normal and decorated, and GPU acceleration continues to work.
How I did it
First find the Flatpak installation:
LOC=$(flatpak info --show-location me.hyliu.fluentreader)Create a working directory and copy
app.asar:mkdir -p ~/tmp/fluent-reader-asar cp "$LOC/files/fluent-reader/resources/app.asar" ~/tmp/fluent-reader-asar/Extract it using Electron's ASAR utility:
npx @electron/asar extract ~/tmp/fluent-reader-asar/app.asar ~/tmp/fluent-reader-asar/unpackedAdd the scaling rule:
printf '\n/* Custom Fluent Reader UI scaling */\nbody { zoom: 1.25; }\n' >> ~/tmp/fluent-reader-asar/unpacked/dist/styles/global.css npx @electron/asar pack ~/tmp/fluent-reader-asar/unpacked ~/tmp/fluent-reader-asar/app-scaled.asarRepack it:
Before replacing anything, make a backup:
cp "$LOC/files/fluent-reader/resources/app.asar" ~/tmp/fluent-reader-asar/app-original.asarClose Fluent Reader completely, then replace the ASAR:
sudo cp --remove-destination ~/tmp/fluent-reader-asar/app-scaled.asar "$LOC/files/fluent-reader/resources/app.asar"Start Fluent Reader normally.
To restore the original:
sudo cp --remove-destination ~/tmp/fluent-reader-asar/app-original.asar "$LOC/files/fluent-reader/resources/app.asar"Important
This is a workaround, not an official Fluent Reader feature.
Any Flatpak update will most likely replace the modified
app.asar, so the modification may need to be reapplied after an update.Also, modifying files inside a Flatpak deployment is obviously not ideal. Keep a backup and be prepared to reinstall/repair the Flatpak if necessary.
The CSS scaling approach itself, however, works surprisingly well.
It would be great if Fluent Reader eventually exposed this as an official setting, for example:
Settings → Appearance → Interface scale → 100% / 110% / 125% / 133% / 150% / ...
The technical workaround was suggested by ChatGPT (OpenAI) and tested and confirmed by myself as a real Fluent Reader user on KDE Plasma/Wayland.
If anyone tests this on GNOME/Wayland, X11, another distribution, a newer Fluent Reader release, or with another scaling factor, I'd be interested to hear the results.
submitted by /u/Upper-Basket-8618
[link] [comments] -
New day. New coffee. What should we work on? Current priorities: wrapping up the new mobile app bug fixes, updating Wavelength, but open to other side quests this week. ☕️
-
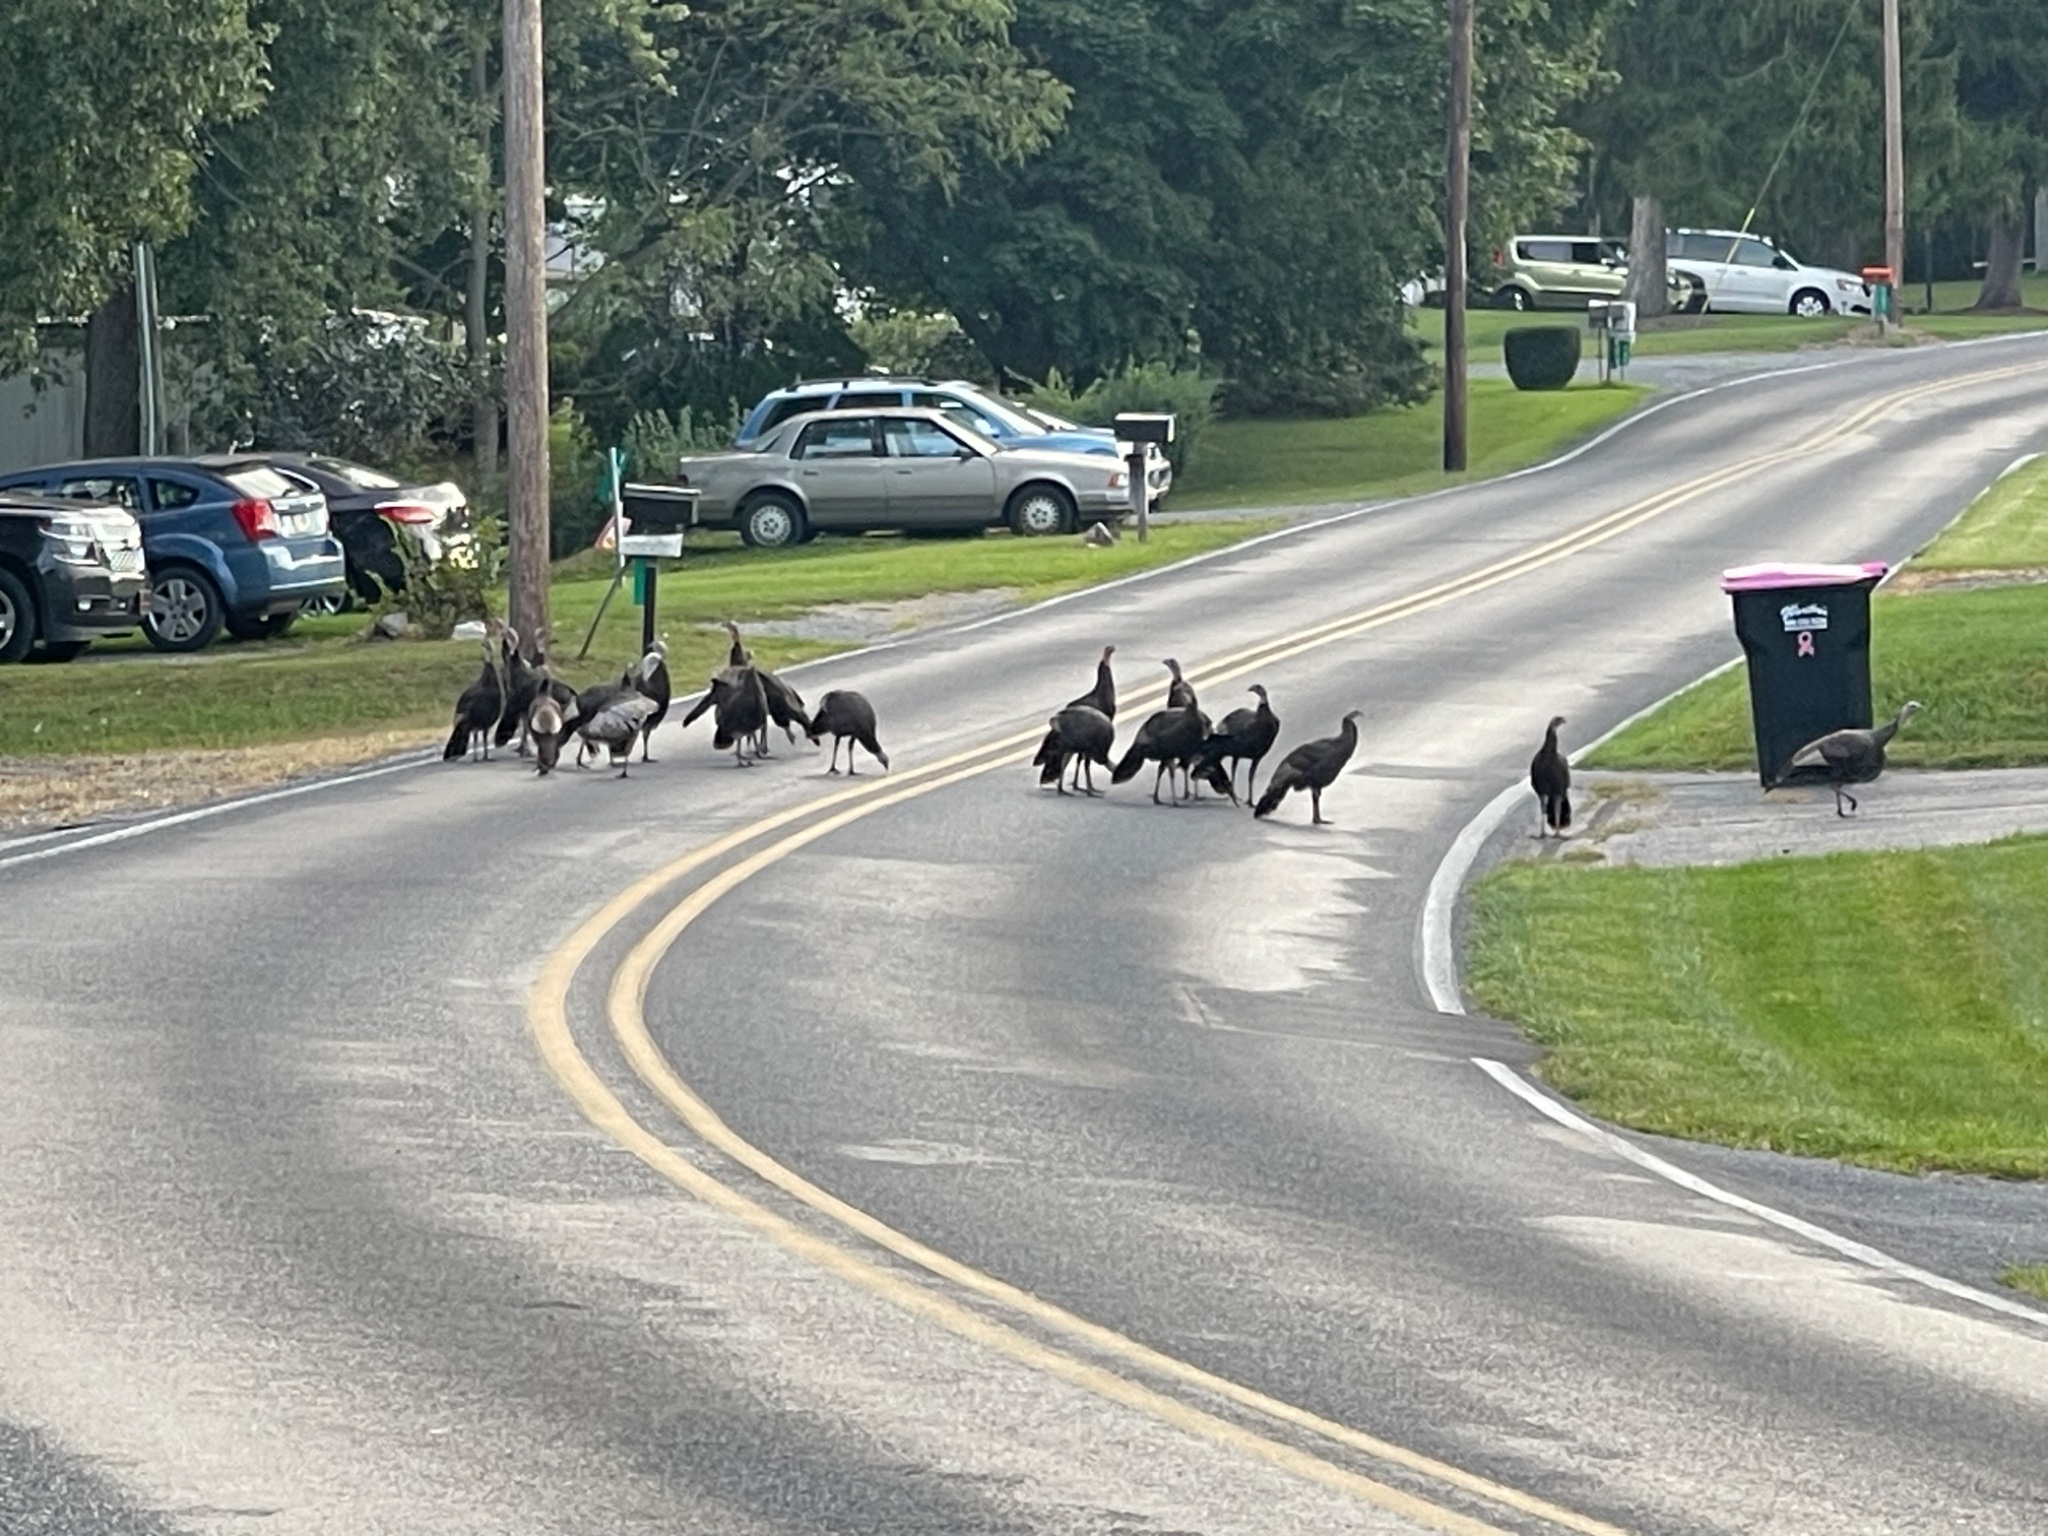
Wild turkeys strutting through the neighborhood

-
Jason Snell blogged a reaction to the latest rumors that the foldable will be called the iPhone Duo! Great name, I really didn't think Apple would go for it. Also happy to see pencil support:
I’ve been wondering about Apple Pencil support on the iPhone for some time now. This product does sort of make sense for it, given the larger canvas of an interior screen.
-
'Tell Everyone:' A Man Died by Suicide After Talking to ChatGPT. His Former Partner Wants to Warn the World About AI
After allegedly becoming emotionally reliant on ChatGPT, Austin died at 40 years old, leaving behind family and friends who loved him. Megan wants everyone to know what happened. -
Do you own a Frame.work 16 laptop ? here is how to run a local-ai stack in one s...
Do you own a Frame.work 16 laptop ? here is how to run a local-ai stack in one shot specifically tuned for this context. https://github.com/rmdes/framework16-local-llm
-
The Man on a Quest to Digitally Preserve America’s Public Restrooms
The Restroom Archive is a museum-style repository of 3D scans of the world's restrooms. -
The 101 Plays Itself . The five lanes of highway 101 in...
The 101 Plays Itself. The five lanes of highway 101 in LA turned into a musical instrument: each car on the live Caltrans camera is a note.
-
Fake Consumer Group Using AI To Generate Fake Support For Paramount Merger
In addition to the $111 billion Paramount/Warner Bros merger just being foundationally bad for creatives, labor, and consumers, the Ellison family-owned company’s executives just keep demonstrating why they’re not really the kind of folks you want dominating the lion’s share of U.S. media. That’s included calling deal critics “antisemitic,” cozying up to foreign authoritarians, constantly […] -
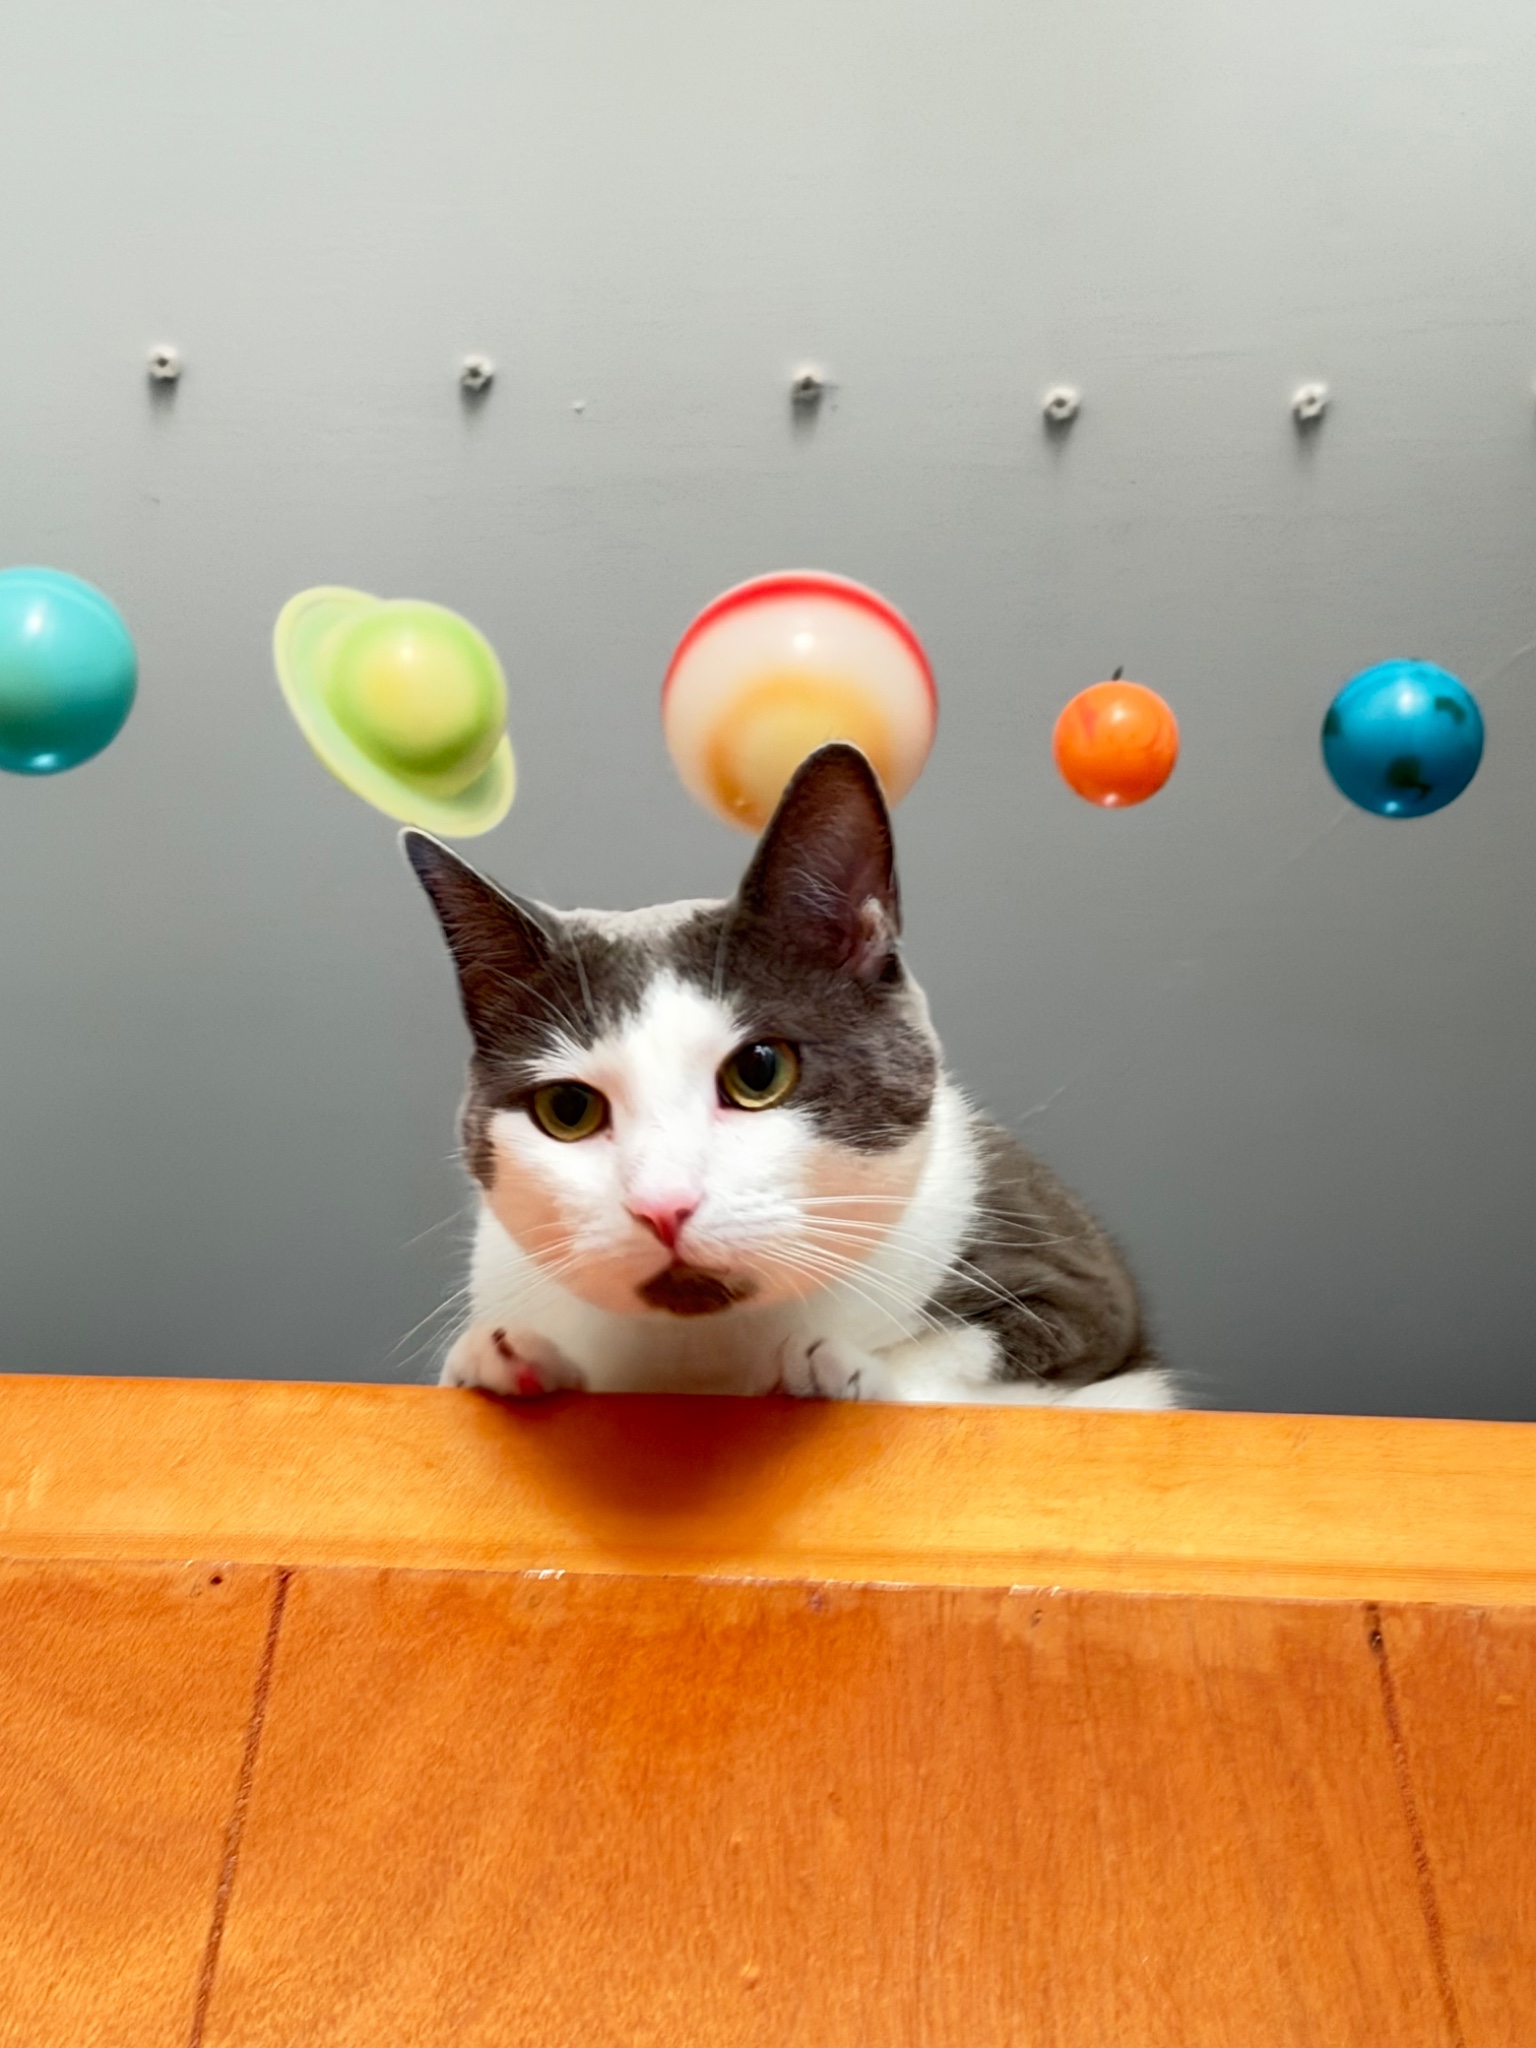
🪐 Ground Control to Major Myles: Please stop knocking the planets out of orbit. 🌏
-
DHS’ Secretive ‘Predictive Policing’ Unit Pulling People Over
Take control of your data footprint risk-free with a 30-day money-back guarantee. Go to https://incogni.com/404Media and use code 404MEDIA for 60% off an annual plan. That's code 404MEDIA at https://incogni.com/404Media We start this week with Joseph’s story about the secretive predictive policing units inside DHS that are analyzing Americans’ financial data and having local cops pull them over. After the break, Jason tells us about the funky shirt designed to fool AI-camera systems. In the subscribers-only section, we talk all about our third anniversary events. YouTube version: https://youtu.be/o0AG6A5MIRg RSVP: Killer Technology With 404 Media A Secretive DHS ‘Predictive Policing’ Unit is Analyzing Americans’ Financial Habits and Pulling Them Over This 'Digital Camouflage' Shirt Confuses AI-Powered Surveillance Cameras We Are Going to Be Okay: A Three Year Anniversary Events Recap Learn more about your ad choices. Visit megaphone.fm/adchoicespdst.fm -
Government updates belong in an open feed
A good blog post from the founder of Open RSS: https://openrss.org/blog/government-updates-belong-in-an-open-feed
The blog's feed: https://openrss.org/blog.rss
submitted by /u/Changaco
[link] [comments] -
Always loved that show… So many great memories that over the years I have seen s...
Always loved that show… So many great memories that over the years I have seen some parts over and over 😊
-
Getting Started with OpenWebUI Pipelines
Interesting stuff I want to read later
-
Larena & Elyse Wynn, Part 1 - Montana Mormons, Sex at BYU, and the “Miracle" of Forgiveness
This week is part 1 with musicians, identical twins, and former Mormons turned dominatrixes Larena and Elyse Wynn, also known by their band name Mothermary. The girls share what it was like being raised in the LDS church, and how “Montana Mormons” may have had a more fear-based culture than Mormons in other parts of the country. They’ll talk about going to BYU Idaho, and how after having sex with her boyfriend—one of the worst sins you could commit in the church—Larena was told by her bishop that she needed to marry her boyfriend in order to not get kicked out of college.
Elyse describes having a similar experience in high school, and how both were told by their bishop to read a book called The Miracle of Forgiveness in order to repent, which basically told them that all the things that make you human are wrong. Elyse explains how she became obsessed with not sinning, why it made her so depressed she couldn’t eat, and how she realized she needed to get out of there.
In part two next week, Larena tells the story of how she got out of her marriage, and how they both came to work as dominatrixes.
See omnystudio.com/listener for privacy information.
podtrac.com -
Risky Business #852 -- Cyber Command wants to buy shells
On this week’s show Patrick Gray and James Wilson are joined by guest co-host Robby Winchester from SpecterOps to talk through the week’s news, including:
- ID verification company IDScan was breached and 153m driver licenses wound up for sale online. Cue the barrage of lawsuits
- The US government plans to pay private contractors to conduct military hacks
- The US accuses China of distillation attacks, a.k.a. forbidden training
- It’s Wednesday, so OpenAI’s agents escaped sandboxes again and passed notes around on a German Wiki
- Much, much more…
This week’s show is brought to you by Sublime Security. Sublime’s head of detection engineering Randy Pargman joins the show to chat about how the company is preparing for prompt injection attacks to move from being largely theoretical to commonplace.
This episode is also available on YouTube
Show notes
- FBI Probes Service Selling 153M+ Drivers Licenses | Krebs on Security
- IDScan sued over alleged data breach affecting 153 million drivers | BleepingComputer
- Senate Considers Allowing Contractors to Conduct Military Hacks | bloomberg.com
- Feds accuse China of ‘systematic’ distillation of U.S. AI models | cyberscoop.com
- Dropbox accounts breached through Lenovo email verification flaw | BleepingComputer
- FBI raises alarm over deceptive phishing campaign targeting prominent people | cyberscoop.com
- Microsoft warns of TerminalFix attacks deploying reverse tunnels | BleepingComputer
- OpenAI agents discussed ways to escape their sandbox on public wiki | arstechnica.com
- OpenAI releases new model that it says triggered internal security measures | NBC News Tech
- Trump may be forced to reveal secret rules feds use for AI safety testing | Social Signals
- Microsoft posts nearly 1,000 bugs for Patch Tuesday as CISA warns two being exploited | therecord.media
- Security Incident – BGP Hijacking – Virtualizor |
- Coder's registry infrastructure compromised to push malicious modules | BleepingComputer
- Pegasus, NoviSpy variant spyware found on devices of Serbian activists | cyberscoop.com
- European parliament members call for slowdown of Serbia’s EU entry over spyware use | CyberScoop
- New pro-Ukraine hacker group targets Russian companies with custom ransomware | therecord.media
- US military disabled ad tracking on troops’ devices following reports of targeted attacks | TechCrunch Security
- New CrowdStrike 'FalconFlank' zero-day grants SYSTEM privileges | BleepingComputer
- A hacker stole $340M in a crypto heist, then returned most of it | TechCrunch Security
- ‘White hat’ hackers take $47 million bounty after $320 million crypto theft | therecord.media
dts.podtrac.com -
Doc and I might not be the same age - but we lived in the same world.
Personally of the view that the story that he writes about is symptomatic of why we have problems as a society.
Agree? Wondering what I am talking about?
-
The Revolutionary Roots That Inspired Tupac Shakur
More To The Story: Last month, Duane “Keffe D” Davis was found guilty of first-degree murder in the death of rapper Tupac Shakur. The verdict came 30 years after Tupac was killed in a drive-by shooting in Las Vegas that for decades remained cloaked in conspiracy theory and mystery. It’s impossible to overstate rapper Tupac’s influence on music and culture in the 1990s. One of the era’s bestselling musical artists, he helped define West Coast hip-hop through vulnerable, introspective lyrics and Black power politics. By his own admission, sports writer Jeff Pearlman is not the rapper’s likeliest biographer. But as he waited for what he called “the big, fat biography” of Tupac, his impatience and long-standing fascination with the rapper got the best of him. So he set out to write it himself. On this week’s episode, Pearlman talks about his book Only God Can Judge Me: The Many Lives of Tupac Shakur; discusses how Tupac’s Black Panther mother, Afeni Shakur, shaped her son; and examines the nuance and mystery that surrounded Tupac’s life and death for decades.
This episode first aired in June 2026.
Producer: Josh Sanburn | Editor: Kara McGuirk-Allison | Theme music: Fernando Arruda and Jim Briggs | Copy editor: Nikki Frick | Digital producer: Artis Curiskis | Intern: Joni Binder | Deputy executive producer: Taki Telonidis | Executive producer: Brett Myers | Executive editor: James West | Host: Al LetsonRead: The 24 Best Books We Read in 2025 (Mother Jones)
Listen: Baltimore Mayor to Trump: Don’t Send Your Troops (More To The Story)
Read: Only God Can Judge Me: The Many Lives of Tupac Shakur (Mariner Books)
Note: If you buy a book using our Bookshop link, a small share of the proceeds supports our journalism.
- Donate today at Revealnews.org/more
- Subscribe to our weekly newsletter at Revealnews.org/weekly
- Follow us on Instagram and Bluesky
dts.podtrac.com -
Reporting Indicates RFK Jr. Directly Intervened To Keep PA Deaths Off CDC Measles Report
The measles outbreak, that began in America nearly two years ago, has only increased in velocity. We recently talked about the deaths of two children in Pennsylvania who both died while infected with measles. I’m altering my language slightly here from that original post in which I described those children as having died of measles […] -
I know I’m really late to this show, but because of the new spinoff we’ve been watching The Big Bang Theory for the first time. A few seasons in. 📺
-
Got this spam text today, just in case there was any question that data centers are going to be a big issue in November:
Manton, if you live at [my address], Republicans have supported a Data Center within 15 miles of you.
-
The AI warnings are coming from inside the lab
Frontier labs make for lousy messengers on AI safety — but it would be foolish to ignore them -
Some thoughts on the Navier–Stokes Millennium Prize Problem
On the Navier–Stokes Millennium Prize Problem introduces an impressive result from OpenAI, who used an unreleased model to produce a resolution to the Navier–Stokes existence and smoothness problem, one of the seven Millennium Prize Problems that have been subject to a $1,000,000 prize since May 24th, 2000.
The discovery is somewhat overshadowed by accusations of skulduggery from Tristan Buckmaster, an NYU mathematics professor who was collaborating on related problems with Levent Alpöge, an accomplished mathematician who currently works for Anthropic.
Tristan's complaint accompanied a hastily published version of their own results. Here's the PDF describing what happened. The very short version is that Tristan and Levent worked on the problem for almost a year, making extensive use of Claude and Codex (mainly GPT-5.6 Sol), then had a breakthrough on August 15th. The mathematical rumour mill kicked into gear and Tristan and Levent heard that OpenAI had heard that Anthropic had resolved "a major open problem", so they reached out and learned that OpenAI had a team working on a related problem, with a similar approach. Quoting Tristan:
I asked when the first prompt had been sent by them. This question was not answered directly by OpenAI for some time. Eventually it was agreed that it had been sent in the past few days, after information about our work had reached OpenAI.
I asked whether the model had been trained on, or had access to, our sessions in Codex, into which we had been putting all our drafts for the whole of this project. I was told the model did not look up user data. I asked again, about training, and I did not get an answer.
It gets more complicated from there. The OpenAI team offered to wait for Tristan to publish, or to have him author a paper about their result, but were clear that Levent would not be invited as a co-author due to OpenAI's competitive relationship with his employer.
Here's how OpenAI described their work:
On Tuesday, September 1, we heard rumors that two Millennium Prize problems had been resolved. Inspired by these rumors and by the step change in performance of our internal model, we launched an effort to evaluate it on all open Millennium Prize problems and a few other high-impact problems. [...]
The agents arrived at their resolution on Saturday, September 5, about 88 hours after the first agents were launched. Lean formalization and verification took an additional 17 hours via GPT‑6 Astra.
Across all attempted problems, the agents sent 4.9 million messages and used about 300 billion output tokens. In the process of resolving the Navier–Stokes problem, the agents sent 2.7 million messages and used approximately 130 billion output tokens.
(We don't know the cost structure of the internal model they used, but 300 billion output tokens at public API prices for GPT-6 Astra would cost $15,000,000.)
Here's where they provide their perspective on Tristan and Levent's work (emphasis mine):
Our effort began on September 1st after hearing a rumor which we later realized was related to Levent Alpöge, an Anthropic employee, and Tristan Buckmaster, a math professor at NYU. After the completion of our full project and Lean verification (on September 6th), believing from the rumor they also had a solution of Navier–Stokes, we reached out to them to offer a concurrent release of our result and to recognize their priority in a joint announcement. [...]
We (the researchers and the agents) did not see any of their work through any means until they released it publicly — in particular, no specific user data was accessed in order to solve this problem. While unlikely, we cannot rule out that de-identified data derived from their usage of our products helped improve our models. However, our proofs differ significantly and even the precise results proved are different in the Euler case (forced vs unforced).
My interpretation of what happened here is that OpenAI heard that some Millennium Prize problems had been solved using LLMs and saw this as an opportunity to demonstrate the power of their latest model, without thinking too hard about the optics of scooping a team who had been using OpenAI's own models to work on this problem for the best part of a year.
This situation appears to mirror what's happening in the world of computer security right now. Anil Madhavapeddy recently pointed out that Just a rumour of a bug is enough to find a security exploit these days, because if someone knows that some software has an unpatched vulnerability, they can set their agents the task of finding it. Is the same now true of mathematics? Just knowing that there is an unpublished solution to a problem might trigger millions of dollars in LLM spending to get there first.
This also highlights one of my ongoing frustrations about how all of this works. When an AI lab says that my data is "used to improve model performance", what does that actually mean?
My two favourite hypothetical questions regarding this used to be:
- If I'm running Codex and one of my API keys accidentally gets consumed in the context, what are the chances that someone else might ask for an API key in the future and get mine back? (I asked someone at OpenAI once and they called this the "regurgitation" problem and assured me that they take great pains to prevent that... but wouldn't describe how.)
- If I brainstorm with ChatGPT about potential new directions for my company, what's the chance that information might be exposed to a competitor in six months' time who asks "what might company X plan to do next"?
My new preferred hypothetical for this is:
- If I use ChatGPT to help me partially solve a Millennium Prize problem, what are the chances that my work will influence training such that a later model helps someone else solve it first?
Via Hacker News.
You are only seeing the long-form articles from my blog. Subscribe to /atom/everything/ to get all of my posts, or take a look at my other subscription options.
-
Some Tech Companies Have Privately Pushed Back On ICE Subpoenas. They Should All Do More.
In a handful of known cases, large social media companies have privately pushed back against Immigration and Customs Enforcement (ICE) subpoenas when the agency tried to unmask anonymous users who tracked immigration activities or criticized the government. As ICE engages in a pattern of illegal and chilling investigations, any resistance is welcome. But social media companies can do […] -
Truth in Humour ..
🔗😂 Daring Fireball: The Onion’s Exclusive Interview With Larry Ellison
-
Feels like the AI world is balancing on a knife's edge. On one side, the worst of big tech's social media addiction machine and an even greater concentration of power. On the other side, the democratization of intelligence and an abundance that lifts all of society. Either outcome seems possible.
-
👁️ 8 Emmys for Widows Bay and I couldn’t even finish the series. Somebody is wrong. No finger pointing now.
-
Cool Cool Cool: Hegseth’s DoD Is Running A Secret Network Of Online Influencers
It would be nice to go a day or two (or three-day weekend!) without being apprised of some new awfulness from this administration. Since that’s not going to happen, let’s check in with the latest shitshow! And here it is: the Pentagon has “enlisted” some X.com influencers to thrust and parry on behalf of the […] -
Rss feed for Linkedin job postings search
Hi! I need recommendations on Rss Feeders that work with LinkedIn Job Search tool. I've tried RSS.app, but when I paste the search url, I get an error message.
submitted by /u/Diligent_Visit_3807
[link] [comments] -
Saw this, loved it and thought of @artkavanagh
-
OpenAI announced a solution to the Navier-Stokes problem, which I had never heard of because I'm not a mathematician, but which is apparently a very big deal:
The question of whether smooth three-dimensional fluid motion can break down has remained unresolved for roughly 90 years.
There is some controversy over whether two human researchers (one at Anthropic) working on similar problems might've accidentally influenced the OpenAI model. It doesn't sound like that's true, but it does feel a little unfair regardless, where credit likely means so much to people.
-
Channel 5 Gave Hunter Biden a List of Its Subscribers’ Emails for Some Reason
A data protection lawyer told 404 Media the sharing was likely illegal, and Channel 5’s own privacy policy explicitly says it won't give subscribers’ emails away to people for marketing purposes. -
Il a bien grandi mon p’tit caoutchouc, d’ailleurs je me demande, ça tiens l’hive...
Il a bien grandi mon p’tit caoutchouc, d’ailleurs je me demande, ça tiens l’hiver dehors?
-
The DOJ’s AI Fair Use Brief Is Correct, But From A DOJ That Has No Credibility
I am never asking the monkey’s paw for a federal government that defends fair use again. For decades on Techdirt, I’ve talked about the absolute necessity of strong fair use, and have been disappointed over and over again at how little the federal government has fought for fair use. For decades, the rare times when […] -
Daily Deal: The 2026 Data Engineering Bundle featuring Databricks
The 2026 Data Engineering Bundle has 7 online courses designed to help learners build skills that align directly with industry expectations. The focus is on practical tools and languages used by data professionals: Python for programming, Pandas and NumPy for data manipulation, foundational certification prep and specialized work with Databricks, an industry-standard platform for data engineering […] -
Did a little Redis housekeeping, cleaning out orphaned records that were sitting around wasting memory. Down to 23 GB of RAM on a 48 GB machine. Still probably too much.
-
Oh... On a plus qu'un seul avion pour le Roi et les Ministres, mais quel pays de dingue tsé!
Lire ça en 2026 et se dire que de fait Jancovici a radicalement totalement raison… On est pas prêt du tout !
-
ICE’s Vetting Standards Are So Low It Can’t Even Be Bothered To Verify The Identities Of New Hires
A whistleblower report delivered to the DHS Office of the Inspector General makes it clear ICE is willing to hire pretty much anyone who applies for the job. Keeping up appearances (and by “appearances,” I mean constantly pushing for 1,500-3,000 arrests per day) is tough when you don’t have the warm bodies to do all […] -
I had a nap yesterday and a late Dr. Pepper, so my sleep was all off. Caffeine really affects me late in the day. Woke up at 2am worried about all sorts of business and social things I can't control.
Let it go. 🎶
-
Might be about time to get a Switch 2... Ocarina of Time remake looks good. 🕹️
-
Looks like Nitter is coming back.
Good for them telling X and their lawyers to go F themselves.
https://nitter.net/X-cancel is already back up
https://xcancel.com/search?f=top&q=elonThis is good news.
submitted by /u/OkDevelopment4438
[link] [comments] -
Ben Thompson in today's Stratechery blog post:
AGI is AI that learns continuously. That’s not the case with current large language models.
I agree with Ben's definition of AGI, but LLM memory is so good now, it's almost indistinguishable from learning. My
~/.codex/memoriesfolder is 7 MB, which doesn't sound like much, but it's only small Markdown files. It's incredible how much it knows. That doesn't even count ChatGPT's dreaming memory system and computer history. -
How am I just now hearing this interview with Jensen Huang? "You're not talking to someone who woke up a loser." 🤣
-
I built a read-it-later tool that uses DOM parsing instead of AI for article extraction - how do you handle full-text RSS parsing without hallucinations?
Hey r/rss folks,
I've been working on a Pocket replacement (Pocket shutting down pushed me).
Most new tools use LLMs to extract article text, but I found they rewrite/mangle the source and add latency + cost.
So I went old-school:
- paragraph density scoring
- <article> / <main> tag tree analysis
- text-to-link ratio filtering
It's deterministic, offline-first, and keeps original text verbatim. No AI.
It is live at https://fetchmarkapp.com and I wrote up the parsing logic on blog.fetchmarkapp.com
Question for this community:
How are you handling full-text extraction for RSS feeds? Are you using Mozilla's Readability.js, custom heuristics, or something else? I'm trying to improve handling for heavy JS sites.
Would love to compare notes.
submitted by /u/Low-Actuary8926
[link] [comments] -
A Secretive DHS ‘Predictive Policing’ Unit is Analyzing Americans’ Financial Habits and Pulling Them Over
404 Media is revealing the name of Border Patrol's predictive policing units, which analyze financial data and have local cops pull people over. The people are not suspected of any particular crime. -
Paramount Caught Using ‘Astroturf’ Group To Drum Up Fake Support For Merger
We’ve well established how the $111 billion Paramount and Warner Brothers merger is terrible for labor, creatives, consumers, and markets. But the kind of behaviors Paramount leadership have been engaged in to sell the deal also give a pretty clear indication what kind of company we’re dealing with, and why they shouldn’t be allowed to […] -
 Scott Hanson is working on a WordPress plugin that displays a FeedLand river — a constantly-updated stream of news items from feeds a FeedLand user subscribes to — on a WordPress page or post. It's important that news flows be part of managing a site. Help Scott make it perfect, WordPress is a very important part of the web. The news tab on my blog home page is an example.
-
J'aime bien le terme "peut-être" dans leur titre.
Peut-être… Qu’on est débile surtout oui!