@admin — following
Follow buttons here act as you, not as @admin.
@admin follows
| Label | Kind | State | Action |
|---|---|---|---|
| @ricardo | local | — | |
| @rmdes | local | — | |
| @paul | local | — | |
| news.rss.chat | source | — | — |
| scripting.com | source | — | — |
| www.techdirt.com | source | — | — |
| simonwillison.net | source | — | — |
| www.manton.org | source | — | — |
| feeds.kottke.org | source | — | — |
| rss.beehiiv.com | source | — | — |
| www.404media.co | source | — | — |
| brilliantmaps.com | source | — | — |
| shellsharks.com | source | — | — |
| www.platformer.news | source | — | — |
| podstandards.org | source | — | — |
| zacharykai.net | source | — | — |
Timeline
-
ICE Worked With Iran To Deport Iranians Back To A Country Trump Repeatedly Claimed Was Harming Iranians
The Trump administration has been working steadily to remove protected status for asylum seekers that even Trump admits are deadly “shitholes.” Trump makes claims about countries that seem to indicate they’re too dangerous to live in, but then insists there’s no reason we shouldn’t be allowed to deport migrants to places where they’re likely to […]Reply source - Reply source
 I've been watching The Pitt, but it can be a bit much, so I went looking for something a bit lighter, and found 9 to 5 on Amazon Prime. Jane Fonda, Lily Tomlin and Dolly Parton are the stars, and Dolly's famous song with the same name is the theme. It's a perfect slice of the world I grew up in. I get it confused with Working Girl which came out eight years later, with a similar theme -- what if women ran the business world, how much better would that be? Working Girl also had a really good theme song, written and performed by Carly Simon.
-
Texas Politicians Slowly Realize Elon Musk Hijacked Billions In Taxpayer Broadband Grants
Back in June I wrote a feature for The Verge about how Elon Musk and Jeff Bezos had convinced Republicans to redirect billions in taxpayer money away from future-proof fiber optic upgrades, and toward their low-Earth orbit (LEO) satellite broadband networks they’d already planned to deploy. Curious behavior for two extremely-rich gentlemen who both repeatedly […]Reply source -
How Cyber Sleuths Tracked a Nigerian Scammer to His Doorstep
Erin West and Paul Raffile went to Nigeria to track down a scammer. They found much more than just his identity.Reply source -
Understanding ChatGPT Work
Reply sourceOpenAI announced ChatGPT Work on July 9th, and have been furiously iterating on it ever since. It is an extraordinarily confusing and very powerful product. Here's what I've figured out about it so far.
ChatGPT Work is actually two products
The more interesting version of ChatGPT Work is the one that runs in the cloud. This can be accessed via chatgpt.com or through the ChatGPT mobile apps. Let's call it Work Cloud.
If you install the ChatGPT desktop app - the app that used to be called Codex - you gain access to a thing called ChatGPT Work that can access files and run programs directly on your computer. Let's call that one Work Local. This one feels more like regular Codex re-skinned to be less intimidating to non-software-developers.
(Update: Work Cloud is also available from the ChatGPT desktop app, via a Where should this chat run? dropdown.)
For the rest of this article I'm going to talk exclusively about Work Cloud.
Work is for paid subscribers only
Right now, ChatGPT Work (in both flavors) is available only to $20/month and up subscribers. Free users and $8/month Go users do not have access.
Work has features that aren't available in Chat
The interface for accessing Work is a tab selector, which presents it as an alternative to Chat:
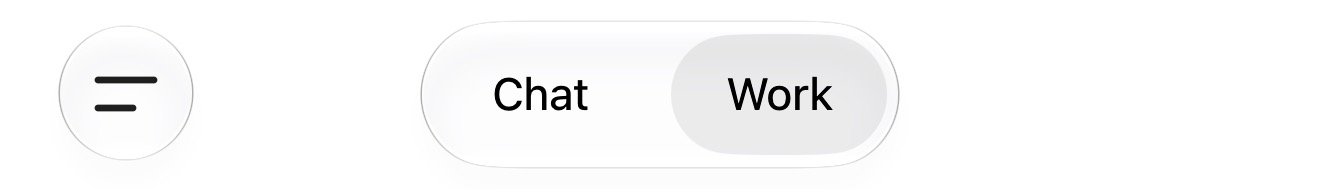
The obvious question is when should I use Chat, and when should I use Work?
OpenAI's official answer to that question is:
Use Chat when you want an answer, explanation, brainstorm, or short draft. Use ChatGPT Work when you want ChatGPT to complete a task with a clear outcome, such as a brief, deck, analysis, recurring update, workflow, or file you can review and use.
I find that almost entirely useless, because I've been using regular ChatGPT Chat for all of those task categories for years!
The better question then is what features does Work have that are missing from Chat?
After extensive experimentation I think I've mostly figured that out:
- Options to use Luna and Terra in place of Sol
- A code execution environment with Internet access
- A headless Chrome browser
- A persistent filesystem shared between sessions
- The ability to publish ChatGPT Sites
- The ability to run sub-agent sessions with Sol, Luna, and Terra
- Scheduled prompt automations (may be in ChatGPT Chat too)
Model selection
In Work, you get the option to pick GPT-5.6 Sol, Luna, or Terra, each with Light, Medium, High, Extra High, Max, or Ultra reasoning levels. You can also pick GPT-5.5 at Light, Medium, High, or Extra High.
These look to be the same models that are available through the OpenAI API.
Chat offers a different selection: 5.6 Instant, Medium, High, Extra High, and Pro (actually Extra High and Pro are only available for $100/month+ subscribers - $20/month subscribers cap out at High). It doesn't explain if those are Luna or Terra or Sol (I'm assuming Sol?). 5.6 Pro appears to be exclusive to Chat, with no equivalent in Work.
My current understanding from using Codex is that Ultra is a special mode that more eagerly delegates to sub-agents.
I believe ChatGPT Work sessions are billed against your Codex allowance, while ChatGPT Chat Sessions get their own, separate allowance. This may help explain the model availability differences.
Code execution with Internet access!
As a long-time fan of the Code Interpreter pattern - pioneered by OpenAI in 2023 - this is by far the most exciting feature of ChatGPT Work (Cloud) for me.
The code execution environment can now talk to the rest of the internet!
ChatGPT Chat can't do this - if you ask it to install additional software packages or interact with websites or APIs that access will be blocked by the container proxy.
(Weirdly, back in January it grew the ability to install packages, but that doesn't seem to work any more. I wish they had better changelogs!)
Claude's equivalent container has allowed restricted internet access since it launched last September. Claude can install packages from PYPI and NPM and clone repositories from GitHub. But that is about it: the allowlist of domains is very short.
ChatGPT Work allows a whole lot more than that. It can be configured with a specific list of allowed domains, but the default appears to be open to all.
This makes Work an incredibly useful tool. You can have it clone GitHub repositories, install their dependencies, then use them to interact with the rest of the web!
A full, headless Chrome browser
Another killer feature of ChatGPT Work is the browser tool. ChatGPT Work can launch a full Chrome instance, load websites, fill out forms, and take screenshots.
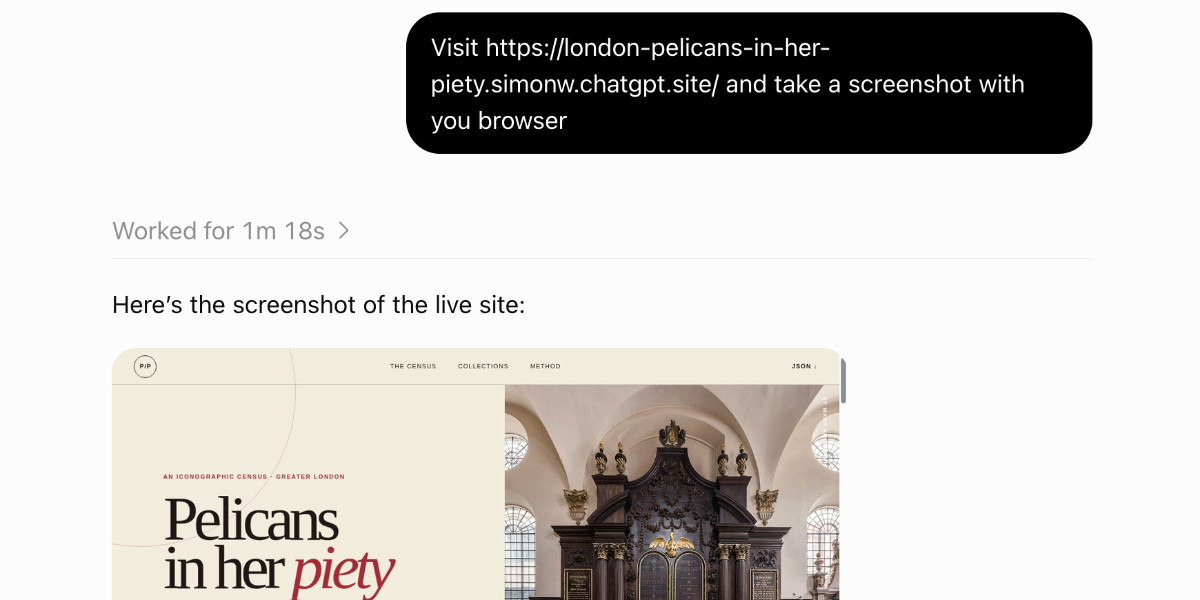
If a site requires sign in the browser can prompt you to take over and enter both passwords and 2FA codes, without round-tripping those credentials through the model itself.
It can even run JavaScript against the DOM of loaded pages. I prompted:
Load simonwillison.net in your browser and extract the headings using JavaScriptChatGPT Work fired up a browser instance and ran the code:
await tab.playwright.evaluate(() => {
  return Array.from(document.querySelectorAll("h1,h2,h3,h4,h5,h6"), heading => ({
    level: heading.tagName.toLowerCase(),
    text: heading.innerText.trim().replace(/\s+/g, " "),
    id: heading.id || null
  }));
});
This feels a lot like my shot-scraper javascript tool, only now I can access it on my phone!
A persistent, shared filesystem
ChatGPT Chat gets a fresh filesystem for each chat session. These cannot be accessed from any other session.
In ChatGPT Work each session gets its own scratch folder - named something like
/workspace/scratch/e00a0a017944- but each of those are persisted across sessions, so you can access files from previous chats. I have 171 folders in/workspace/scratchright now!As far as I can tell that
/workspacevolume is mounted to all Work sessions that are currently running - file edits from one can be instantly seen by the others. They don't seem to share the same process space though, and localhost servers running in one can't be accessed from another.ChatGPT Sites
ChatGPT Work has the ability to build and deploy entire websites, using Cloudflare Workers. These can have HTML and JavaScript and can run server-side features too, including stateful features on top of Cloudflare D1 and R2.
Here's a simple site I built with this feature:
london-pelicans-in-her-piety.simonw.chatgpt.site
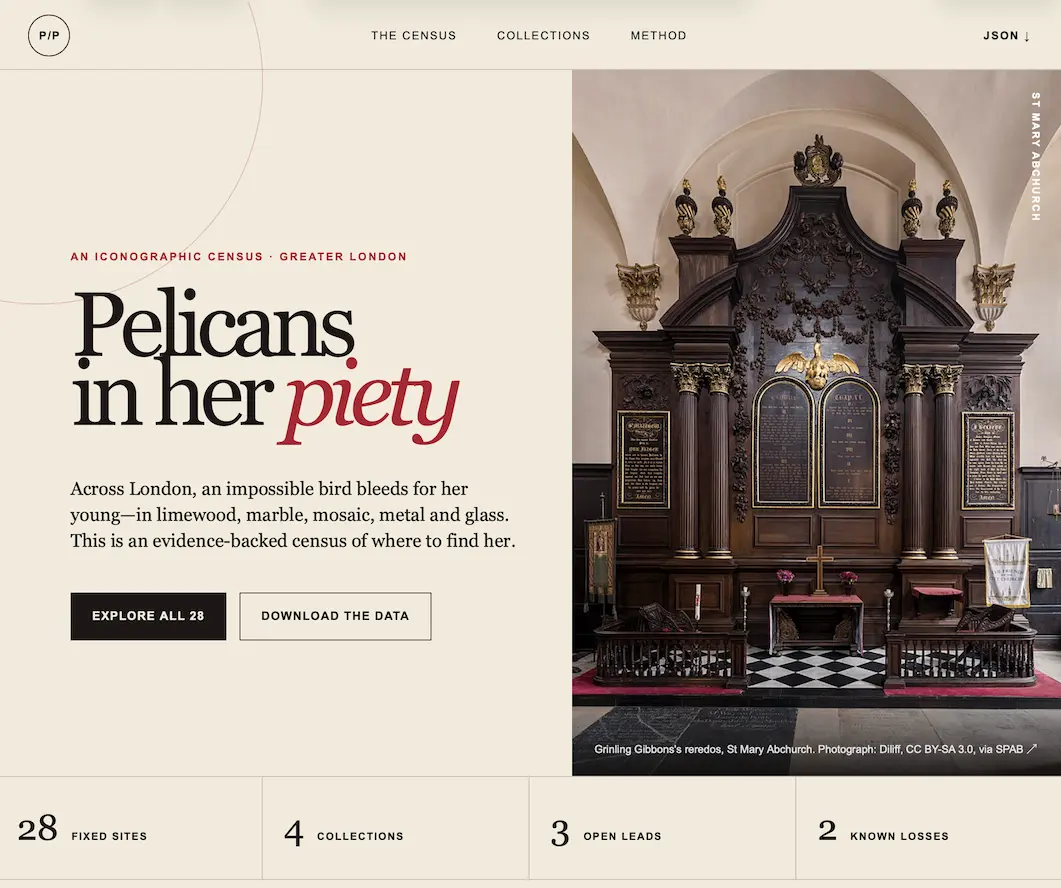
My prompt was:
Figure out all of the places in London with a pelican in her piety, then turn that into a JSON file and build a ChatGPT sites site about them(A pelican in her piety is a fascinating piece of medieval Christian imagery - once you know about them you'll find them all over the place.)
These sites default to being private to the user that created them, but you can make them public and (on team plans) share them with other specific individuals.
Sub-agents with Sol, Luna, and Terra
There's not much to say about this one. ChatGPT Chat can't run sub-agents. ChatGPT Work can. This is very much a power-user feature: if you are running a complex project that can benefit from multiple parallel agents working together, Work can do that.
Scheduled prompt automations
Another feature that seems to have migrated from regular ChatGPT to ChatGPT Work at some point. You can prompt ChatGPT Work like this:
run a search to see if Waymo have announced a launch date for Half Moon Bay every day at 8amThis will schedule a prompt to run on that frequency. These prompts can decide that nothing interesting has happened, or they can decide to notify you of some new information.
Update: Actually this seems to work in ChatGPT Chat as well.
It's still worth noting here though, as it can be used in conjunction with other ChatGPT Work exclusive features. You can set a scheduled task to update a ChatGPT Site on an hourly basis, for example.
Is this safe?
An open question for me right now is how safe all of this stuff is.
My lethal trifecta model warns about the risks inherent in any agent system that combines access to private data with exposure to untrusted content and a way to communicate stolen information back to an attacker.
ChatGPT Work combines all three!
I'd love to hear more from OpenAI about how they protect ChatGPT Work sessions against prompt injection attacks. I expect their answer is the same auto-review mechanism as Codex.
OpenAI could make this a lot less confusing
Figuring this all out took way more work than it should have.
I think there are two key problems here:
- OpenAI explain Work in terms of what it's for, not what it actually does
- OpenAI still insist on hiding their system prompts and tools descriptions
If the ChatGPT Work documentation included the exact system prompt and tool descriptions used by the agent I wouldn't have needed to write this post.
A list of all the tools
Shortly after publishing this article I had an idea. I started a fresh Work session and prompted:
Build a site that lists every one of your tools - nearly grouped into categories - and for each one explain what it does. Try to exactly duplicate arguments and tool descriptions where possible. Design aesthetic should be technical docs, minimal flareHere's the site it built, which includes details of 223 registered tools - though 6 of those are from my own personal MCPs served via datasette-mcp.
And a whole lot of Skills
I noticed that the only browser-related tool in the list was web.run, which has methods for running searches, opening URLs, and clicking links, but didn't look like the full story in regards to headless browser automation.
This made me suspicious that something was missing, so I told the ChatGPT Work session that built that tools reference site:
Add full copies of every skill to the website (separate pages linked to from the homepage)It turns out ChatGPT Work uses a lot of skills - 44 in fact!
The control-browser skill explains how the browser works:
Run browser setup code through the Node REPL
jstool. In this environment the callable tool id typically appears asmcp__node_repl__js. [...]The ability to interact directly with the browser is exposed through the
browser-clientruntime via theagent.browsers.*API. Before trying to interact with it, you MUST emit and read the complete documentation returned byawait browser.documentation()in one go.So I told Work:
Add the full output of await browser.documentation() to the bottom of the /skills/control-browser page
And now you can read that on /skills/control-browser as well.
A few more interesting Skills:
-
documents for creating
.docxfiles -
imagegen with tips on creating images with the
image_gentool - pdf for both reading and rendering PDFs
-
Spreadsheets for manipulating
.xlsx,.xls,.csv,.tsv - sites:sites-building for creating ChatGPT Sites
- openai-docs for answering questions about itself
- data-analytics:build-dashboard for building data dashboards
You are only seeing the long-form articles from my blog. Subscribe to /atom/everything/ to get all of my posts, or take a look at my other subscription options.
-
Funniest/Most Insightful Comments Of The Week At Techdirt
This week, MrWilson scores another double-win with both top spots on the insightful side. In first place, it’s a piece-by-piece response to a commenter who defended ICE’s failed illegal raid on an immigration law office: In second place, it’s a comment about the first two measles deaths of 2026: Then: “Nobody has died. It’s not […]Reply source -
Google's Calling Lake Ontario 'Lake America' Now
Google Maps announced on Saturday it would start reflecting the change for U.S.-based users.Reply source - Reply source
 I've been watching Season 1 of The Pitt, and as its reviews said, it's great drama, and there are lots of episodes. I like shows like this because they're simulated communities, we come to know the characters, and think about them even when we're not watching. Before too long we'll have AI programming that makes these shows like software, the stories assemble around the characters, and then are generated the same way ChatGPT generates the art we call slop, which will someday not be a pejorative the same way sick and junk aren't negative terms today. So we'll be able to call up new episodes of The Wire or The Sopranos or The Pitt any time we like. We'd be missing the fun of discussing the latest episode with friends, or maybe we'll have bot-invented friends too who will simulate having watched the episode you just watched, which leads us to another masterpiece of entertainment, The Matrix. On the other hand, I've watched The Wire at least five times all the way through, and even though I know what they're about to say in a lot of places, I do forget the sub-plots so at least some of it can be new each time. And btw, finally an episode of Silo that's was surprising that I didn't see coming. I read the books, so I feel like I should watch the show, but until the latest episode I was uninterested in any of the characters. Finally there's a plot to think about!
- Reply source
An absolutely delicious temperate cloud-free day in the Catskills, so I got up from the computer and enjoyed.
-
This Week In Techdirt History: August 23rd – 29th
This Week in 2016 This Week in 2011 This Week in 2006Reply source -
Thousands of Interstellar Objects May Be Lurking in Our Solar System
The Sun has likely passed so close to other stars in the past that it captured thousands of small interstellar objects from alien systems, reports a new study.Reply source -
Buc-ee’s Decides The Right Response To Pushback On Its Trademark Bullying Is To Invoke Partisanship
We’ve been detailing the trademark bullying ways of Buc-ee’s, famous gas station and convenience store chain in the American south and infamous IP bully, for over a year now. Buc-ee’s seems to think that any semi-related business that has branding that involves a cartoon animal or in any way references beavers somehow violates its trademark […]Reply source -
‘Right To Repair’ State Laws Continue To Surge, But Enforcement Remains Nonexistent
There’s still a massive effort afoot to implement statewide “right to repair” laws that try to make it cheaper, easier, and environmentally friendlier for you to repair the technology you own. All fifty states have at least flirted with the idea, though only Massachusetts, New York, Texas, Minnesota, Colorado, California, Oregon, and Washington have actually passed laws. US PIRG […]Reply source -
Ctrl-Alt-Speech: Move Fast And Settle Things
Ctrl-Alt-Speech is a weekly podcast about the latest news in online speech, from Mike Masnick and Everything in Moderation‘s Ben Whitelaw. Subscribe now on Apple Podcasts, Overcast, Spotify, Pocket Casts, YouTube, or your podcast app of choice — or go straight to the RSS feed. To get extended episodes with additional coverage, support us on […]Reply source -
Pete Hegseth And His Department Of Unconstitutional Revenge Lose Again In California
When Pete Hegseth declared Anthropic a national security risk because it wouldn’t agree to his dangerously unethical demands for what Claude should be able to do, Anthropic sued to challenge the directives. One of the challenges was brought in the Northern District of California, where Anthropic has now notched another significant win. While the previous […]Reply source -
Daily Deal: Raspberry Pi Pico With Ultimate Starter Kit
The SunFounder Raspberry Pi Pico With the Ultimate Starter Kit offers a rich IoT learning experience for beginners aged 8 and up. With over 450 components, 117 projects, and expert-led tutorials, this kit makes learning microcontroller programming and IoT engaging and accessible. It also features 27 video lessons by renowned educator Paul McWhorter, simplifying microcontroller programming […]Reply source -
School Asks Cops To Stop Using Stun Gloves On Its Students
Compliant Technologies probably would have preferred to keep flying under the radar. But a gaudy new no-bid contract with ICE (worth up to $20 million!) made it impossible. Prior to ICE’s big purchase, it may as well have never existed. It only had a few clients, and those few clients purchased a few pairs for […]Reply source -
Behind the Blog: The Complete Idiot's Guide to Flamin' Hot Slop
This week, we discuss cool old books, new toys for ICE, and a boardwalk slop invasion.Reply source -
ICE Plans to Spend Millions on Boston Dynamics Dog Robots
ICE wants the robot dogs to improve “officer safety.”Reply source - Reply source
 Manton wants to know why Marc Benioff chose the name Claudeforce for his brand-merge of Salesforce and Claude. My two cents. Claude is a great name. I think that’s ultimately what he bought. His customers just want to be able to check the box – we’re using AI. Boss is happy. When I was coming up as a young dude in tech, the old saying was “No one ever got fired for buying IBM.” Today, in 2026, it’s Claude in place of IBM. My father worked in marketing at IBM in Armonk, so I heard a lot about their strategies that meant the IBM brand would be kicking ass forever. All things must pass. But in the early days of the PC industry, IBM sure had the power. Kind of like the US going to war with Iran in 2026. In the end IBM wanted to get rid of Microsoft, but Billg had the last laugh.
-
Republicans Stumble In Bid To Flood Midterm Airwaves With Discounted Ads
Back in June, the Supreme Court ruled 6–3 in National Republican Senatorial Committee v. Federal Election Commission that federal limits on coordinated expenditures by political parties violate the First Amendment. Which is every bit as stupid and corrupt as it sounds. Previously, under the Federal Election Campaign Act (FECA), political parties were subjected to strict […]Reply source -
Irony: Catholic Bishops Tell FL Officials To Respect Its Religious Liberty To Not Accept Religious Exemptions For Vaccines
The country is continuing to reel from multiple infectious disease outbreaks in America, even as childhood vaccination rates continue to fall. Measles, cyclosporiasis, whooping cough: you don’t actually need me to go on. With RFK Jr. using his position as Secretary of HHS to further muddy the waters on vaccines and their safety, some states […]Reply source -
How AI agents "radicalized" a top Meta exec into quitting her job
Clara Shih on how AI will soon displace the first few rungs on the career ladder — and why she left Big Tech to do something about itReply source -
Comparing Nixon’s Attacks On The Press To Trump’s
This article is republished from The Conversation under a Creative Commons license. Read the original article. In his White House Correspondents’ Association dinner speech on July 24, 2026, President Donald Trump made his usual diatribes against the news media. He derided the “failing” New York Times and reiterated his complaint that CNN reporter Kaitlan Collins doesn’t smile enough. He […]Reply source -
LA Mayor Karen Bass The Latest Democrat To Wimp Out On Paramount Merger
The unpopular Paramount Warner Brothers merger should have been a perfect opportunity for Democrats to demonstrate they are finally serious about stuff like media consolidation, right wing propaganda, media reform, and antitrust after decades of policy incoherence. Instead, numerous prominent California Democrats have been buckling to Paramount demands aimed at settling a 12-state antitrust lawsuit […]Reply source -
The AI ‘Ghosts’ Contaminating Academic Publishing
“The academic record is being quietly haunted” by researchers with names like Elena Vasquez and Marcus Chen.Reply source -
Oracle Helped Kneecap Section 230, Then Bought 15% Of A Company That Needs It.
Six years ago, when Trump first tried to force ByteDance to sell TikTok’s US operations to his billionaire buddy Larry Ellison at Oracle, we wondered if this would finally get Oracle to change its tune on Section 230. While not as widely known outside of Silicon Valley, Oracle has been a driving force behind the […]Reply source -
Daily Deal: The 2026 Canva Creator Mastery Bundle
Take your design skills to the next level with the 2026 Canva Creator Mastery Bundle, a powerful all-in-one course for modern creators and business owners. This program teaches you how to use Canva effectively to produce professional-quality visuals for any purpose. You’ll explore practical design techniques, creative workflows and branding strategies that make your content […]Reply source -
Flock Claims It’s The First Company To Expose Police Misuse Of Surveillance Tech
Flock Safety is hurting. It spent the early part of its career pitching plate reader tech to people who honestly didn’t need it: HOA supervisors and gated communities. Then it realized there was far more money to be made by courting governments, rather than the richest parts of the private sector. A few years later […]Reply source -
The Tragedy and Ecstasy of AI Companions (with Bridget Todd)
In her new audiobook, Love at First Prompt: AI and the Future of Intimacy, Bridget Jones and Michael Amato unpack how real people are using chatbots to seek connection, in an era when tech companies are constantly trying to exploit our innermost worlds.Reply source -
Cocomelon's Studio Tells Its Artists to Start Experimenting With AI
Moonbug Entertainment, which makes Cocomelon, Blippi, and other popular content for children, says it will begin using AI but will always have a 'human in the loop.'Reply source -
Businesses Go Viral for Making Signs Without AI
In the wake of the ChatGPT flyer pandemic, some businesses are differentiating themselves by making signs the old school way.Reply source -
Florida ‘Deputy of the Year’ Used Flock to Stalk Ex, Held Gun in Her Mouth, Did a Nazi Salute
The deputy resigned after an investigation uncovered an alleged history of racism, stalking, and sexual abuse.Reply source - Reply source
My WordPress mirror site stopped updating on August 12. It's now updating once again. I'll try to watch it more carefully.
-
Iowa AG Brenna Bird Makes Silly, Empty Legal Threats To Try And Save Larry Ellison’s Paramount Merger
As we’ve been noting, billionaire Larry Ellison’s effort to dominate what’s left of corporate media is facing some headwinds after 12 states filed an antitrust lawsuit against his planned $111 billion merger between Paramount and Warner Brothers. As we’ve also noted, this is a giant turd of a deal, the debt from which will indisputably […]Reply source -
Two Die In Pennsylvania Of Measles Marking The First Deaths Of 2026
Last year, as decades of work by RFK Jr. to undermine vaccines with false links to deaths and autism culminated in his appointment to lead HHS, America saw the largest resurgence of measles cases in something like three decades. Three people died, including two children, all unvaccinated. Kennedy mostly ignored the outbreak from the beginning […]Reply source -
Meta settles with the states over child safety failures
Will significant changes to Facebook and Instagram be enough to beat back a global wave of bans?Reply source -
Meta Just Paid Nearly $17 Billion To Make Sure It Gets To Write The Kid Safety Rules For Every Other Social Media Platform
By now you’ve almost certainly heard the news that Meta has settled with 52 state and local Attorneys General who had sued the company in some form or another over child safety on Meta’s platforms. The headlines are all covering the basics: the years-long case these states filed against Meta ends, and Meta pays somewhere […]Reply source -
ICE Tries, Fails To Illegally Raid An Immigration Law Office; Settles For Empty Threats Instead
The thing about raiding law offices is that they tend to be filled with people who actually know the law. A bunch of opportunistic ICE officers thought they might be able to talk their way into an illegal search, but that initiative (is that the word for this?) died out almost immediately when the interloping […]Reply source -
A Student Said He Was a Hobby Plane Spotter. He Was Allegedly Taking Photos for the Chinese Government
Weiheng Zeng originally said he took photos of planes for an aviation fan website. Later he admitted a suspected Chinese government official had given him specific locations in the U.S. to go photograph.Reply source -
Scientists Discover Vast Underground 'Anomaly' on Mars
Scientists have used a novel technique to detect a major temperature asymmetry under the surface of Mars that could shed light on the evolution and past habitability of the red planet.Reply source -
How AI Watermark Mandates Could Unmask Journalists Who Never Touched AI
Imagine a scenario where a documentary filmmaker, in the course of making the documentary, captures some damning footage of corporate malfeasance, which she wishes to share with an investigative reporting organization anonymously. Should we be concerned that mandates on AI watermarking might reveal who she is, even if she’s not using AI at all? Last […]Reply source -
Daily Deal: The Essential MATLAB & LabVIEW Mega Bundle
The Essential MATLAB and LabVIEW Mega Bundle has 9 courses to help you improve your skills in programming and visualization. You’ll learn the basics of each and then go through hands-on courses building apps, learning about data analysis and visualization, and more. It’s on sale for $30. Note: The Techdirt Deals Store is powered and […]Reply source -
As Flock Vandalism Goes Mainstream, One Grand Jury Says Alleged Flock Vandal Did Nothing Wrong
Flock Safety has been on the wrong side of the press cycle — if not the wrong side of history — for most of the last couple of years. Flock’s automated license plate readers (ALPRs) are more comprehensive than many of those previously deployed by law enforcement agencies. Not only do they capture plate/location data, […]Reply source - Reply
I've updated my feedland page with 13 aggregator and firehose feeds from Bear Blog, Pinboard, Scour, Hacker News and others.
A good way to use these is to put them all in one folder in your reader and filter for keywords based on your interests.
Full list of feeds and link on my blog:
- Reply
Test post
- Reply
Link penalties on social media platforms
Although I’ve known for a while that social platforms make posts with links in them less visible, I didn’t know until recently just how much they did it. So, here’s a run down of how much different platforms penalise links and how you can work with it.
(Although the real answer is of course to use platforms that don’t penalise links, sometimes you have to go where people are)
https://paul.jottit.org/link-penalties-on-social-media-platforms
- Reply
What is the most frustrating thing about RSS?
https://www.reddit.com/r/rss/s/uXhg2u6noX// #p-mas
-
not even counting anymore
Kill the algorithm in your head: Let's set up RSS readers and get news we actually want in 2026
https://scour.ing/redirect/https://www.pcgamer.com/software/kill-the-algorithm-in-your-head-lets-set-up-rss-readers-and-get-news-we-actually-want-in-2026?utm_source=rss// #p-mas #p-bs
- Reply
aaaand again
an ode to rss feeds
https://raccoongirltalkstotheworld.bearblog.dev/an-ode-to-rss-feeds/// #p-mas #p-bs